Search Engine Optimization Tutorial for Beginners: A 2026 Foundation
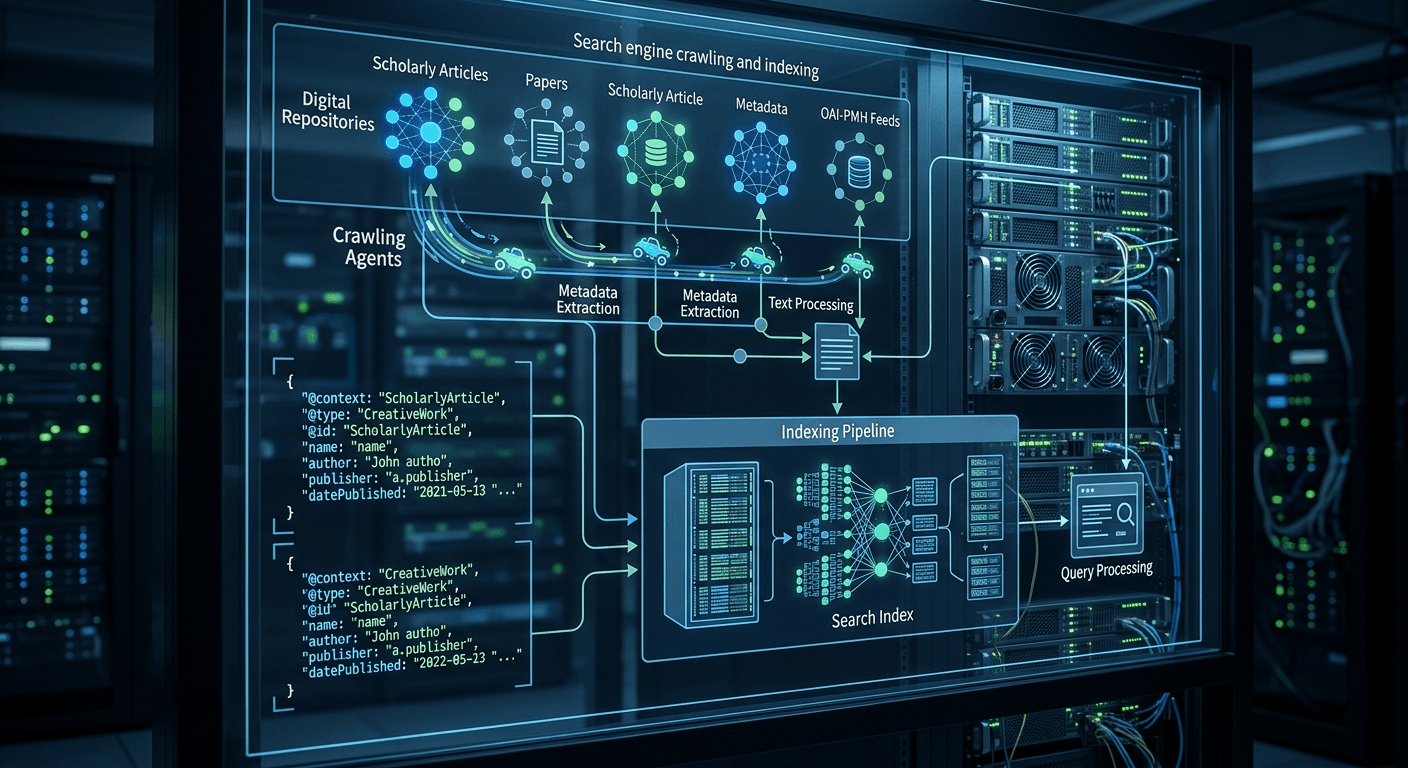
Most university administrators and nonprofit digital teams operate under the assumption that publishing a rigorously researched, 3,000-word report inherently guarantees search visibility. The reality is that search engines do not read reports for brilliance; they parse the relationships between entities and code. If an academic paper lacks machine-readable schema, clear heading hierarchy, and external domain validation, search crawlers simply move on. A practical search engine optimization tutorial for beginners must bypass the myth of keyword density and focus on the mechanical workflow of making mission-critical content accessible, indexable, and authoritative for both traditional search algorithms and generative AI retrieval models.
Quick Summary
Search engine optimization (SEO) is the systematic configuration of digital content so that search crawlers and AI models can reliably retrieve it as the definitive answer to a user's query.
- Technical architecture dictates whether a page is physically discoverable by crawlers.
- Content format must map directly to the searcher's established intent.
- AI visibility requires explicit data structuring, moving past unstructured text blobs.
- External validation from trusted institutional domains builds canonical authority.
Table of Contents
- 1. How a Search Engine Optimization Tutorial for Beginners Handles Intent
- 2. Technical Architecture Determines Discoverability
- 3. Structuring Content for Generative AI and Algorithms
- 4. Validating Entity Authority Through External Citations
- 5. Measuring Performance Through Indexing Analytics
- Common Pitfalls & Troubleshooting
- FAQ
1. How a Search Engine Optimization Tutorial for Beginners Handles Intent
The foundation of any effective search workflow begins with query intent mapping. This is the process of identifying exactly what a user expects to find when they type a phrase into a search bar, and aligning that expectation with the research or services your institution provides. Search engines categorize intent into informational, navigational, commercial, and transactional queries. For a university or nonprofit, most target queries are informational - users seeking definitive answers, datasets, or policy breakdowns.
Why format dictates ranking capacity
Search algorithms measure user behavior and semantic relevance. If a user searches for "climate grant application requirements," clicks your page, and immediately returns to the search results, the engine registers a failed interaction. You cannot trick an algorithm into ranking a donation page for an informational query. You must build a dedicated resource that directly answers the specific question. Any reliable seo marketing guide will emphasize that intent dictates format: if the search results for a query show primarily listicles and step-by-step breakdowns, your dense, theoretical policy brief will struggle to rank because the engine has already determined that users want a list.
Actionable check: Take the primary keyword you want a page to rank for and search it in an incognito browser window. Look exclusively at the format of the top three results. If those pages are glossaries and you are trying to publish a 50-page PDF, you must restructure your content to match the established format.
2. Technical Architecture Determines Discoverability
Technical SEO ensures that search engine crawlers can physically access, render, and index your website's pages. Without a sound technical foundation, the most rigorously researched content remains entirely invisible. This discipline focuses on server responses, URL structures, crawl budgets, and client-side rendering methods.
Server latency and crawler behavior
Crawlers like Googlebot allocate a specific "crawl budget" to your domain. This serves as a strict limit on how many pages they will request during a given period. If your server is slow, the bot leaves before discovering your priority content. The same happens if your site architecture traps the crawler in endless redirect loops and paginated archives. Modern digital ecosystems frequently utilize headless, API-first content delivery systems. They separate the backend database from the frontend presentation. This decoupling ensures minimal server latency and clean source code. Bots can then parse the text and schema. They do this without executing heavy client-side JavaScript.
Actionable check: Log into Google Search Console and navigate to the "Pages" report under the Indexing tab. Look specifically for URLs categorized as "Discovered - currently not indexed" or "Crawled - currently not indexed." If mission-critical research papers appear in these lists, your server may be responding too slowly, exhausting the crawl budget before the page can be fully processed.
3. Structuring Content for Generative AI and Algorithms
Writing for search visibility requires organizing information so that both traditional algorithms and generative AI models can parse the semantic relationships between concepts. This means discarding standard paragraph styling and implementing a strict, predictable document hierarchy built on semantic HTML and structured data.
Moving beyond unstructured text blobs
Generative AI models like ChatGPT and Gemini do not "read" an article; they map the statistical proximity of words through Retrieval-Augmented Generation (RAG) and rely heavily on document structure to assign weight to facts. An H2 heading signals a major entity, while a bulleted list beneath it signals the supporting attributes. When a nonprofit publishes an impact report as a flat PDF or a heavily stylized webpage without HTML equivalents, they lock their data inside a format that crawlers struggle to parse. Instead, content must be broken down into clean markup utilizing JSON-LD schema to explicitly define organizations, authors, and datasets. A standard content marketing blog might survive with loose formatting, but authoritative institutional data requires machine-readable precision. Organizations can also rely on specialized platforms offering free AI visibility for nonprofits and universities to automate the deployment of schema across headless environments.
Practical rule: Never use a heading tag simply to make text larger or bolder; headings must strictly outline the document's logical hierarchy, with H3s only ever acting as sub-components of the H2 immediately above them.
Actionable check: Disable CSS in your web browser or use a text-only extension to view your most important publication. If the document does not read like a coherent, naturally flowing outline with clearly nested sections, search crawlers are actively misinterpreting its core subject.
4. Validating Entity Authority Through External Citations
Search engines cannot independently verify the accuracy of a complex academic claim or a nonprofit's localized impact metrics. Instead, they rely on a mathematical proxy for trust: backlinks from other authoritative domains. Entity authority is the measure of how trusted your organization is within a specific topic cluster, determined almost entirely by who chooses to cite your work.
The mechanics of institutional trust signals
When an established government domain (.gov) or a recognized peer institution (.edu) links to your research, the search algorithm passes a portion of the linking site's canonical authority to your page. This mechanism, known as PageRank, is not about sheer volume; a single citation from a globally recognized research institute carries significantly more weight than fifty links from low-quality web directories. Operating an effective seo marketing blog for an institution requires avoiding spammy outreach tactics and focusing instead on digital PR - publishing proprietary datasets, original survey results, or specialized reference tools that naturally compel journalists to cite the source. Over time, these consistent citations teach the algorithm that your domain is the definitive entity for that subject.
Actionable check: Export your current backlink profile using an indexing tool like Ahrefs or the Google Search Console Links report. Filter the referring domains to identify which specific pieces of your historical content attract the highest-quality institutional links, and structure your future publication calendar around those proven formats.
5. Measuring Performance Through Indexing Analytics
Publishing structurally sound content is only half the workflow; the other half is measuring how search algorithms actually respond to it. Search analytics provide the raw data required to refine intent mapping and diagnose technical failures before they cause severe traffic drops.
Moving past vanity metrics in search evaluation
Many organizations fixate entirely on organic traffic volume without understanding what drives it. If your traffic spikes because a generic blog post ranks for a high-volume, low-relevance query, that traffic offers zero value to your institutional mission. Any comprehensive seo digital marketing course will instruct you to evaluate Impressions, Click-Through Rate (CTR), and Query relevance rather than just top-line user counts. Furthermore, "Average Position" is a highly deceptive metric. A page ranking position 1 in your local region but position 50 internationally averages out to 25. Evaluating queries manually reveals the true story of how users find you.
Actionable check: Open Google Search Console's Performance report and apply a regex filter to exclude any queries containing your organization's brand name. Analyzing this non-branded search data is the only accurate way to determine if your topical authority is actually growing among users who did not already know who you are.
Common Pitfalls & Troubleshooting
When organic traffic stagnates, the symptoms often look identical: flatline analytics and declining daily impressions. However, the root causes require entirely distinct interventions.
Keyword Cannibalization
- Symptom: Two or more pages on your domain frequently swap places in the search results for the exact same query, with neither page breaking into the top five positions.
- Diagnosis: The search engine is confused about which page serves as the definitive answer, splitting your domain's authority across multiple URLs. For prolific university publishers, this is the most frequent real cause of stalled rankings.
- Fix: Audit the competing pages. Consolidate the duplicate information into a single, comprehensive master page, and set up a permanent 301 redirect from the discarded URLs to the newly consolidated resource.
Orphaned Content
- Symptom: A newly published, highly detailed research report receives zero organic impressions over several months despite having excellent technical metrics and fast server response times.
- Diagnosis: The page lacks internal links from other relevant pages on your domain. Crawlers navigate via links; if a page exists in isolation without pathways leading to it, the search engine assumes it holds little value.
- Fix: Identify three to five existing, high-authority pages on your domain that discuss related topics. Add contextual internal links from those established pages directly to the newly published report.
Index Bloat
- Symptom: Server logs show search engine bots actively crawling your site, but your priority pages take weeks to appear in search results, while unimportant pages are indexed immediately.
- Diagnosis: Your content management system is automatically generating and allowing indexation of low-value URLs, such as author archives, category tags, or paginated internal search results, exhausting your daily crawl budget.
- Fix: Implement aggressive "noindex" tags on thin, auto-generated archive pages and configure your robots.txt file to block crawlers from accessing internal site-search parameters.
Render-Blocking Client-Side Rendering
- Symptom: The text of your article is perfectly visible to a human user in a browser, but Google Search Console's URL inspection tool shows a blank page or missing paragraphs.
- Diagnosis: Your site relies heavily on client-side JavaScript to load core text content, and the search bot is either timing out or choosing not to execute the script during its initial rendering pass.
- Fix: Shift mission-critical content delivery to server-side rendering (SSR) or static site generation (SSG) so that the raw HTML source code contains the full text immediately upon the server's response.
FAQ
How long does it take for technical search optimization to show tangible results? Search engine optimization generally requires three to six months to manifest measurable changes in traffic. This delay occurs because search engines must first discover your technical updates, allocate crawl budget to re-process your pages, and recalculate your domain's authority against historical data and competitor movements.
Do nonprofit institutions need a different search strategy than commercial businesses? Yes. While technical fundamentals remain identical, nonprofits and universities must prioritize informational intent and entity authority over transactional product keywords. The strategy relies heavily on publishing definitive research, policy breakdowns, and structured datasets that attract citations from other academic or governmental entities.
How do AI chatbots impact traditional search engine traffic? Generative AI interfaces like ChatGPT capture a large portion of zero-click informational queries. For organizations, the optimization goal shifts from purely driving website clicks to ensuring that your verified data is cited as the canonical source by the AI model's Retrieval-Augmented Generation processes.
What is the difference between crawling and indexing in search behavior? Crawling is the physical process of discovery, where a bot requests a URL and downloads its code. Indexing is the subsequent process of analyzing that code, determining its relevance, and storing it in the search engine's active database to be served as an answer to a user's query.